Your “AI feature” started as a Python script that calls OpenAI. Six months later it is twelve files, a Celery queue nobody understands, and a product manager asking why token costs doubled after you added document upload.
RocketRide (rocketride-org/rocketride-server) packages that mess into something you can draw, version, and run. About 20,000 GitHub stars, MIT license, and a C++ execution engine under a visual pipeline builder in VS Code. Pipelines are portable .pipe JSON: RAG, OCR, agents, embeddings, and a pile of provider nodes without gluing each API by hand.
What it is
RocketRide markets itself as an open-source AIDE, an AI Development Environment. Think less “chat window,” more “data pipeline canvas” for LLM workloads. Source nodes accept webhooks, chat, or file drops. Middle nodes handle chunking, vector stores, NER, PII scrubbing, and model calls. Response nodes return results. You wire types on lanes, run from the canvas, and trace token use before you scale.
The runtime is multithreaded C++. Nodes are mostly Python you can read and extend. The VS Code extension is the control plane; Docker image ghcr.io/rocketride-org/rocketride-engine listens on port 5565 by default for self-hosted engines. Python and TypeScript SDKs call the same pipelines from your apps. MCP support exposes pipelines as tools for coding agents.
They also sell RocketRide Cloud. Self-hosting is the on-prem path with the same .pipe files, which matters when prompts, documents, and embeddings should not leave your network.
Why self-host?
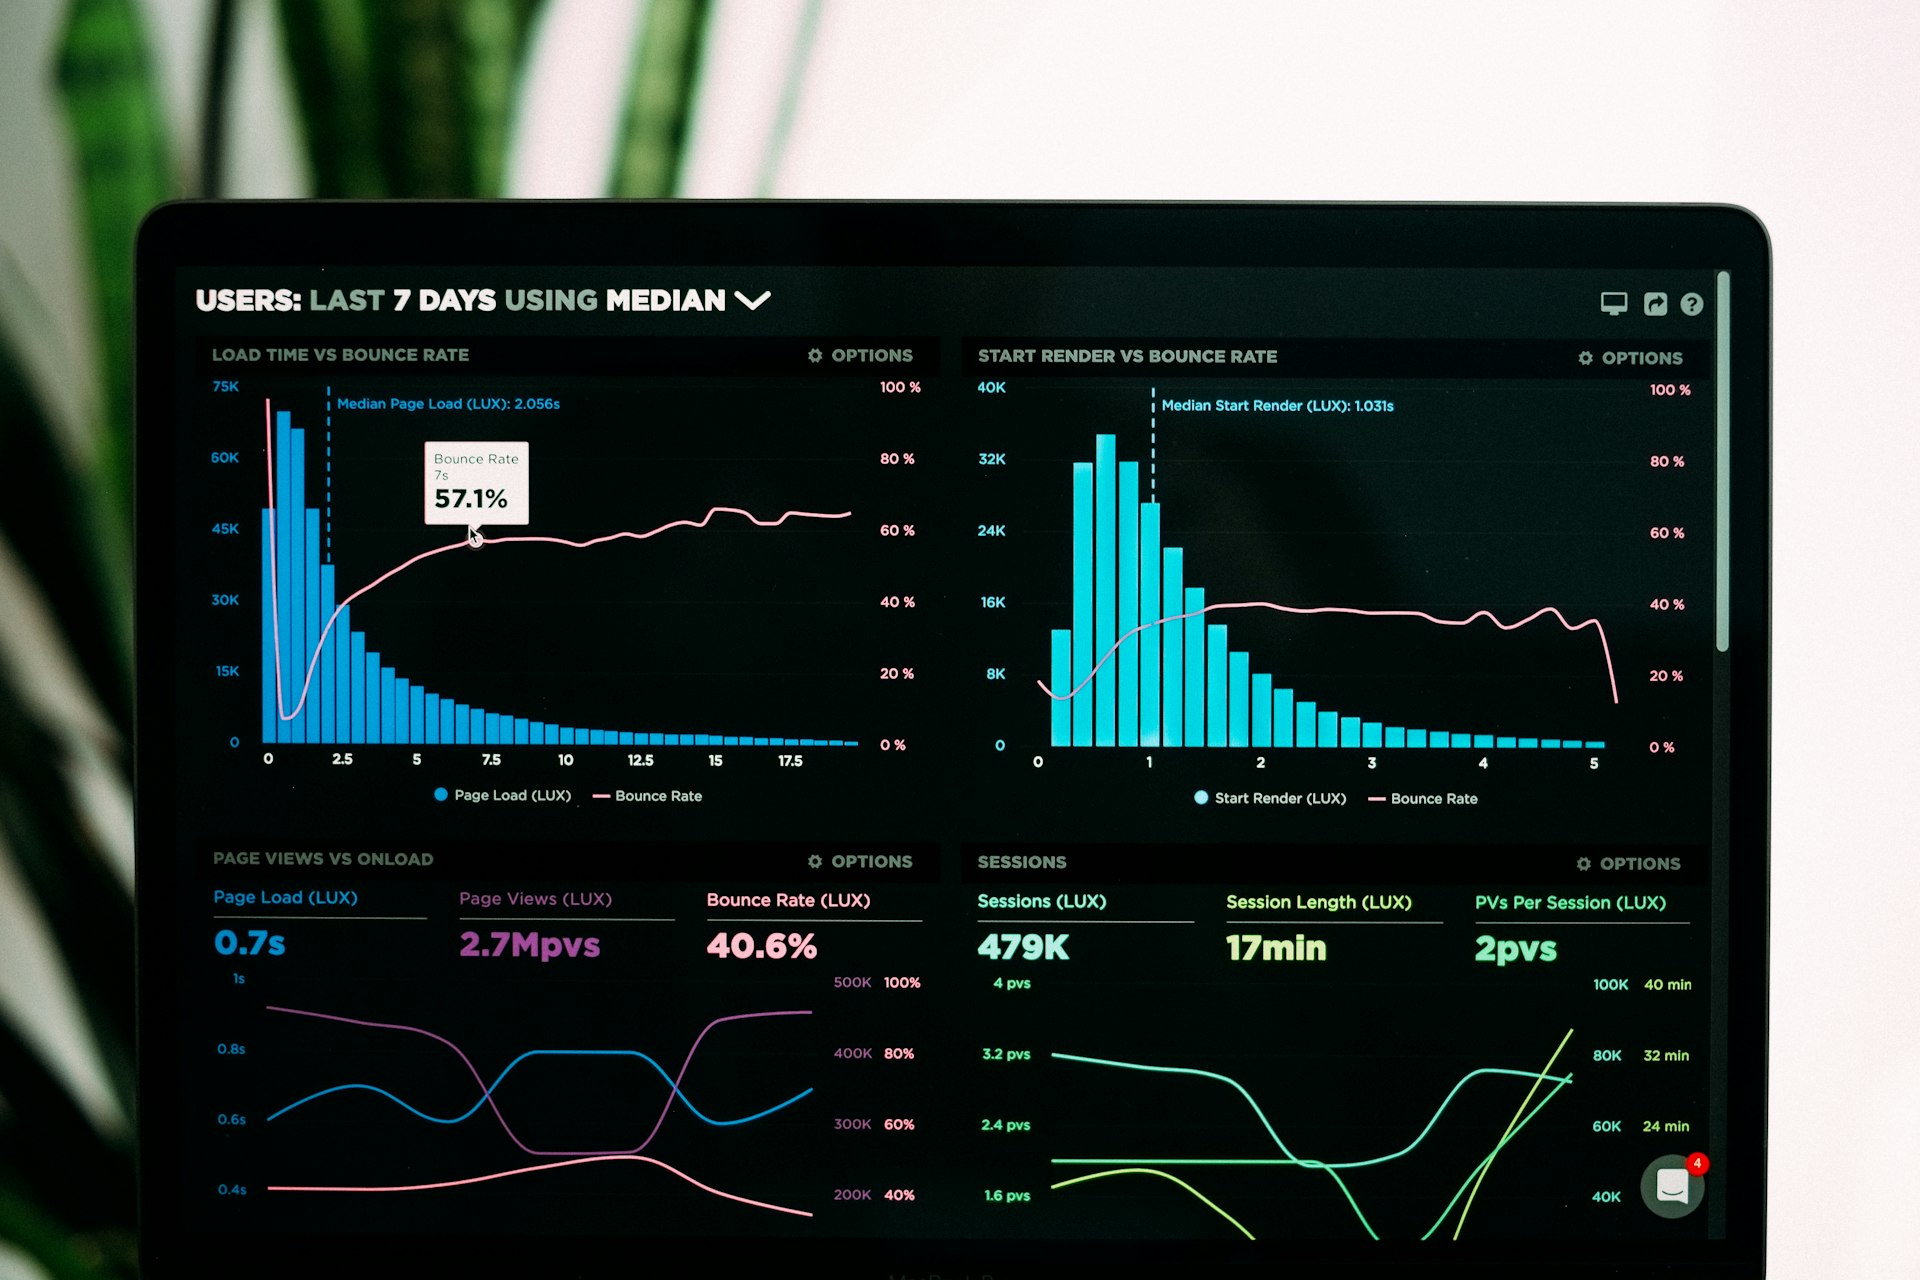
Pipeline observability includes what models saw, how long each step took, and which documents entered RAG. Canadian teams building client-facing AI features may need that trail on Canadian VPS or private cloud, not only in a US-hosted control plane. MIT code with no enterprise edition gate is rare in this space; you still pay for GPUs, inference APIs, and ops.
Compare with NanoClaw (messaging bots in containers) or n8n (general automation). RocketRide is deeper on multimodal AI pipelines, vector search, and agent loops with built-in tracing aimed at ML-shaped throughput.
What running it takes
Budget a real build box: Docker or bare metal, enough RAM for concurrent pipelines, disk for document ingestion, and outbound access to whichever LLM providers you wire in. Local dev can start from the VS Code extension’s “Local” mode; production is Docker, Helm, or their engine image behind TLS. Back up .pipe definitions in git; back up vector stores and secrets separately.
Good fit / skip it
Good fit: teams shipping RAG or document automation, dev shops already in VS Code, engineers who want pipelines reviewable like infrastructure code.
Skip it: a single ChatGPT wrapper with no pipeline, teams allergic to Docker and C++ build chains, orgs that want fully managed AI with zero engine maintenance.
Hosting in Canada
Run the engine on a Docker-capable VPS or dedicated GPU host if you run local models. Keep ingestion and vector DB volumes in Canada when contracts mention data residency. Lock down webhook URLs and API keys like any production AI surface.
Bottom line
RocketRide is self-hosted AI pipeline infrastructure: visual .pipe workflows, C++ runtime, SDKs, and observability for people who outgrew one-off scripts. Install the engine, version your pipelines, and treat AI like software engineering instead of magic glue.
Talk with Swift Host for Canadian VPS and Docker hosting. We are in St. Albert and actually answer the phone.