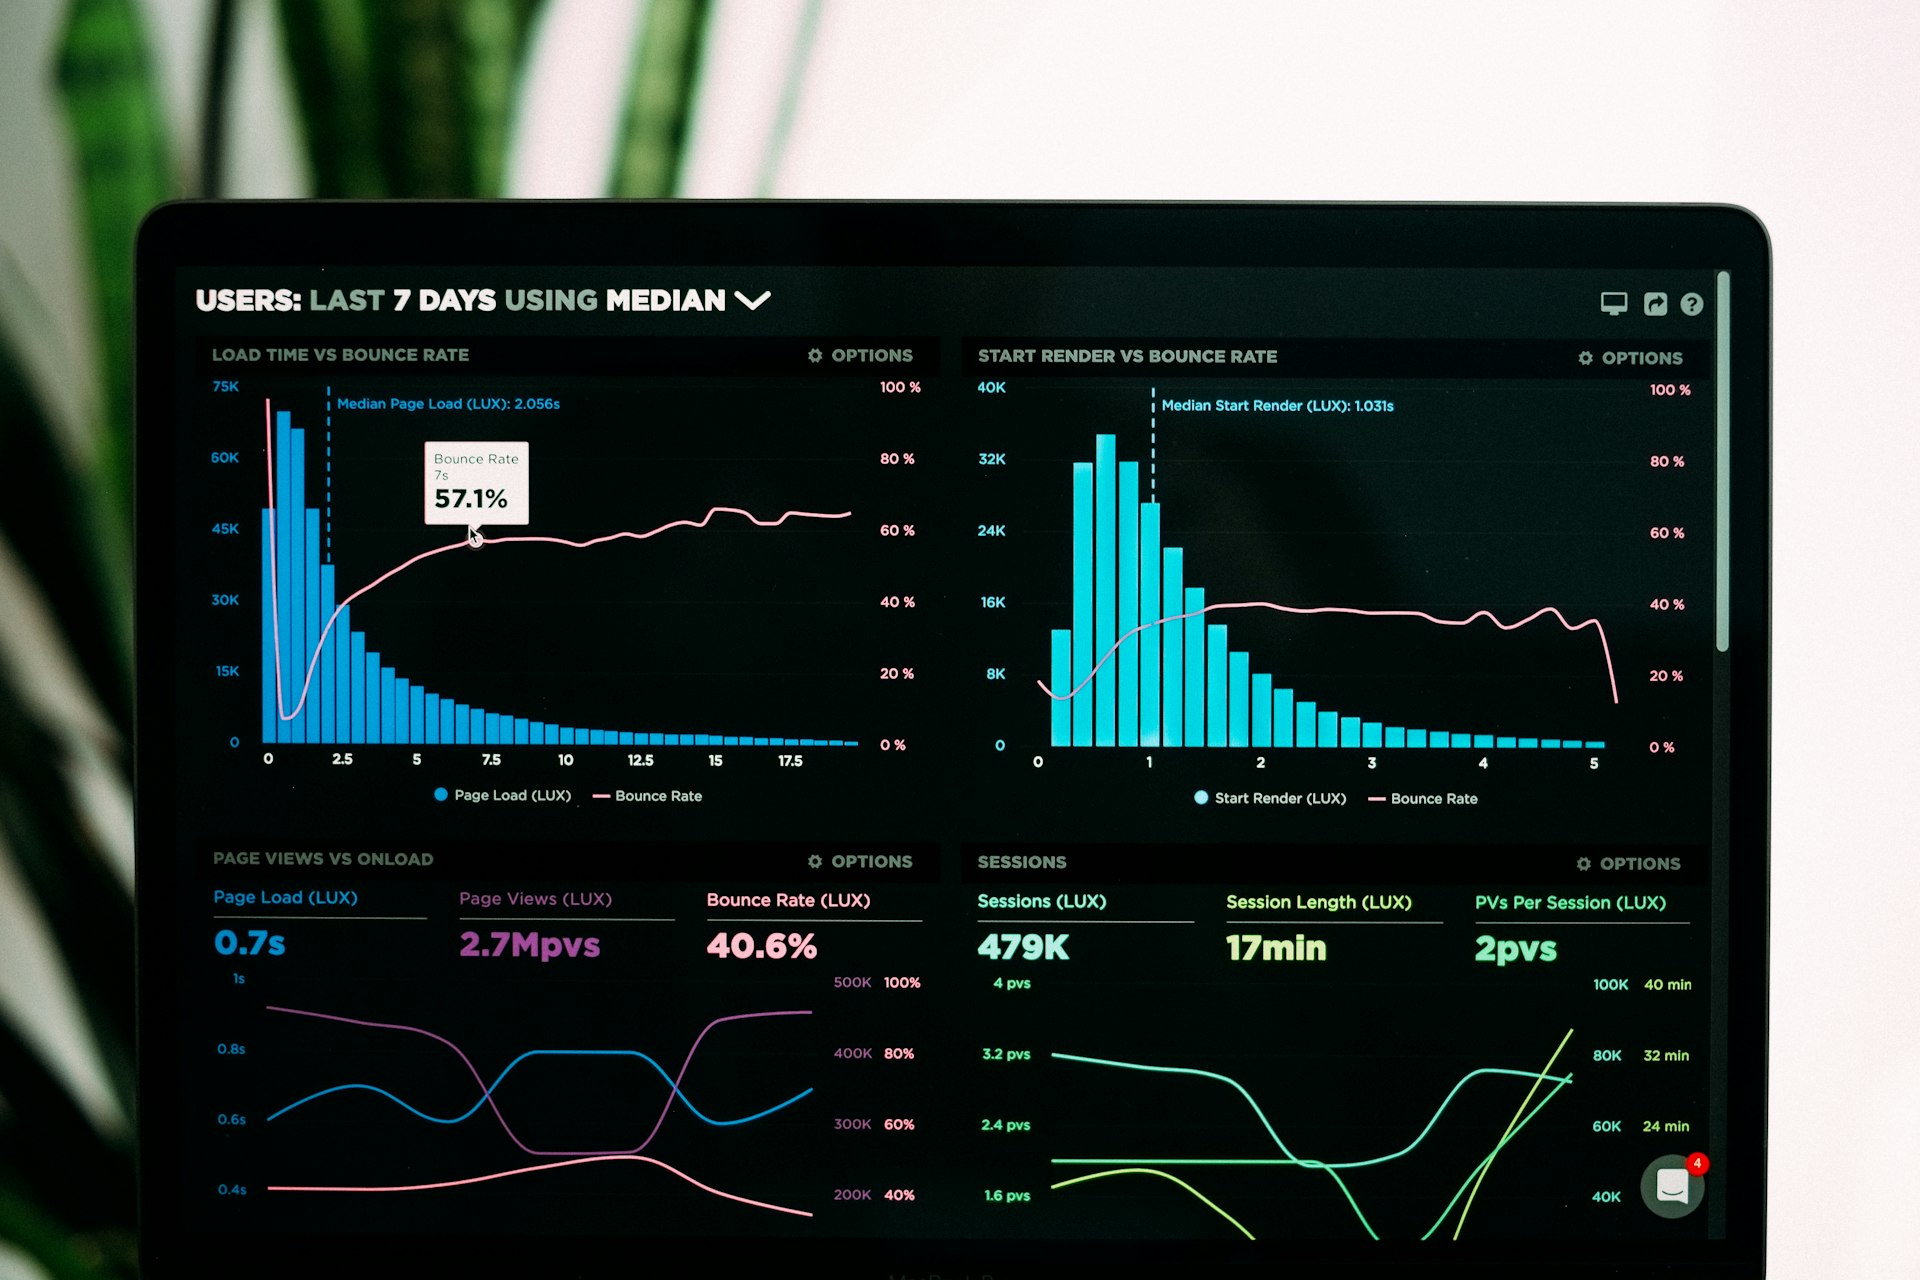
Your product team asks for a dashboard that refreshes in seconds, not after tomorrow's warehouse job. Marketing wants to slice last hour's clickstream by region. Ops wants the same database to survive a traffic spike without a five-figure cloud analytics bill. That is usually where someone mentions a column store, a stream processor, and three different SaaS contracts.
Apache Druid is the open-source option a lot of teams land on when they want one system built for sub-second aggregates on event data. ~14k GitHub stars, Apache-2.0, born at Metamarkets and now a top-level Apache project. Druid is a real-time analytics database: ingest streaming or batch events, store them in a columnar format tuned for time-series and high-cardinality dimensions, and query through SQL, JDBC, or HTTP while a built-in web console handles loaders and cluster health.
What it actually does
Think events in, fast GROUP BY out — not a general OLTP database and not a replacement for every Postgres workload. Druid shines when timestamps and dimensions (user id, country, SKU, status code) dominate and you need interactive dashboards or high-concurrency API queries.
Typical pieces in a production cluster:
- Ingestion — Kafka, Kinesis, or batch files through Middle Managers (or the newer Indexer path on Kubernetes). The Overlord schedules tasks; segments land in deep storage.
- Query path — Brokers fan out to Historical nodes (hot segments on local disk + memory) and merge results. Routers give you one front door and host the web UI.
- Coordination — Coordinators balance segments across Historicals; ZooKeeper handles service discovery and leader election.
- Deep storage + metadata — S3-compatible object storage or HDFS for segment files; PostgreSQL or MySQL for metadata (Derby is fine for a single-node toy cluster, not for production).
You get DruidSQL, native JSON queries, integrations with Superset, Grafana, Tableau, and friends, plus point-and-click ingestion wizards in the console. Streaming supervisors keep Kafka topics flowing in without hand-rolling cron importers.
Public write-ups over the years tie Druid to clickstream analytics, application performance monitoring, network telemetry, and fraud dashboards — anywhere "how many, grouped by what, in the last fifteen minutes" is the question that never stops.
Why self-host?
Cost at scale. Managed real-time analytics pricing often tracks ingested volume and query scans. When you already pay for Canadian compute and object storage, running Druid on your metal can beat renting another warehouse tier — if you have someone who can operate Java services and ZooKeeper.
Data stays yours. Event streams can include IPs, account ids, and payment-adjacent metadata. Keeping segments and metadata DB on infrastructure you control (and in-country) is a straight PIPEDA story for many Canadian product companies, especially when cloud analytics regions are US-only.
Latency and integration. Self-hosted Druid sits next to your Kafka cluster, your VPC, and your internal Grafana. No egress hop through a vendor API for every dashboard refresh.
No license surprise. Apache-2.0 upstream. You still pay in RAM, SSD, and engineer time — Druid is not a weekend Docker sidecar like a notes app.
What running it takes
Start local with the official quickstart or Docker tutorial to learn the mental model. Production usually means multiple JVMs split across Master (Coordinator + Overlord), Query (Broker + Router), and Data (Historical + ingestion) roles — or Kubernetes with the druid-operator.
Honest sizing talk:
- Memory-heavy Historicals — hot segments memory-map from disk; starving Historical RAM shows up as slow dashboards long before CPU maxes out.
- Deep storage is mandatory — treat it as backup and rebalance glue, not optional. Plan retention: what stays on Historical SSD vs what you query cold from deep storage only.
- ZooKeeper (or Curator-compatible stack) — another moving part to patch and monitor; do not skimp on backups for metadata DB and ZK.
- Ingest + query contention — at higher load, split Middle Managers away from Historicals so batch backfills do not fight live queries.
JDK requirements track current Druid releases (check the repo before you bake an AMI). Patch releases matter; this is security-sensitive infrastructure if it faces your network.
Who it's for (and who should skip it)
Good fit: teams with Kafka (or similar) already flowing, BI builders who outgrew Postgres rollups, observability platforms, ad/network analytics, internal "how is the product doing right now" consoles.
Maybe skip it: if your analytics are nightly batch only and Redshift-or-equivalent already sleeps well, Druid is extra ops. If you need strong transactional updates row-by-row, use Postgres. If nobody on staff will own JVM tuning and segment balancing, a managed offering — or a simpler time-series DB — may save sleep.
Hosting it in Canada
We help clients map VPS and dedicated footprints when the hard part is RAM for Historicals and fast NVMe, not installing a PHP app. Pair Druid with Canadian object storage for deep storage, keep metadata in-region, and peer Brokers on private networking to your ingest pipeline.
Tell us your event rate, retention window, and whether you are streaming or batch-first if you want a sanity check before you size a cluster — or if you need a staging single-node stack to prove the dashboard before production roles multiply.
Running event analytics on your own terms? Talk with Swift Host — we are in St. Albert and actually answer the phone.