Your backup cron ran at 3 a.m. Or it didn't. The script printed "done" to a log nobody opened. Three weeks later you find out the dump job has been failing silently because a disk filled up. Endpoint monitors would still show the site as green.
Healthchecks (healthchecks/healthchecks, ~10.5k GitHub stars, BSD-3-Clause, Python/Django) is a dead-man's-switch for cron and background work. Jobs ping a unique URL (or send a tiny email) when they finish. If a ping does not show up inside the period plus grace window, Healthchecks alerts you. The same codebase powers the hosted product at healthchecks.io; you can run it yourself.
What it actually watches
Uptime Kuma and Gatus poke URLs and ask "is this up?" Healthchecks asks the opposite: "did this job check in?" That is the right question for restic, mysqldump, n8n scheduled workflows, certificate renewals, and any Python worker that can die without taking the web server with it.
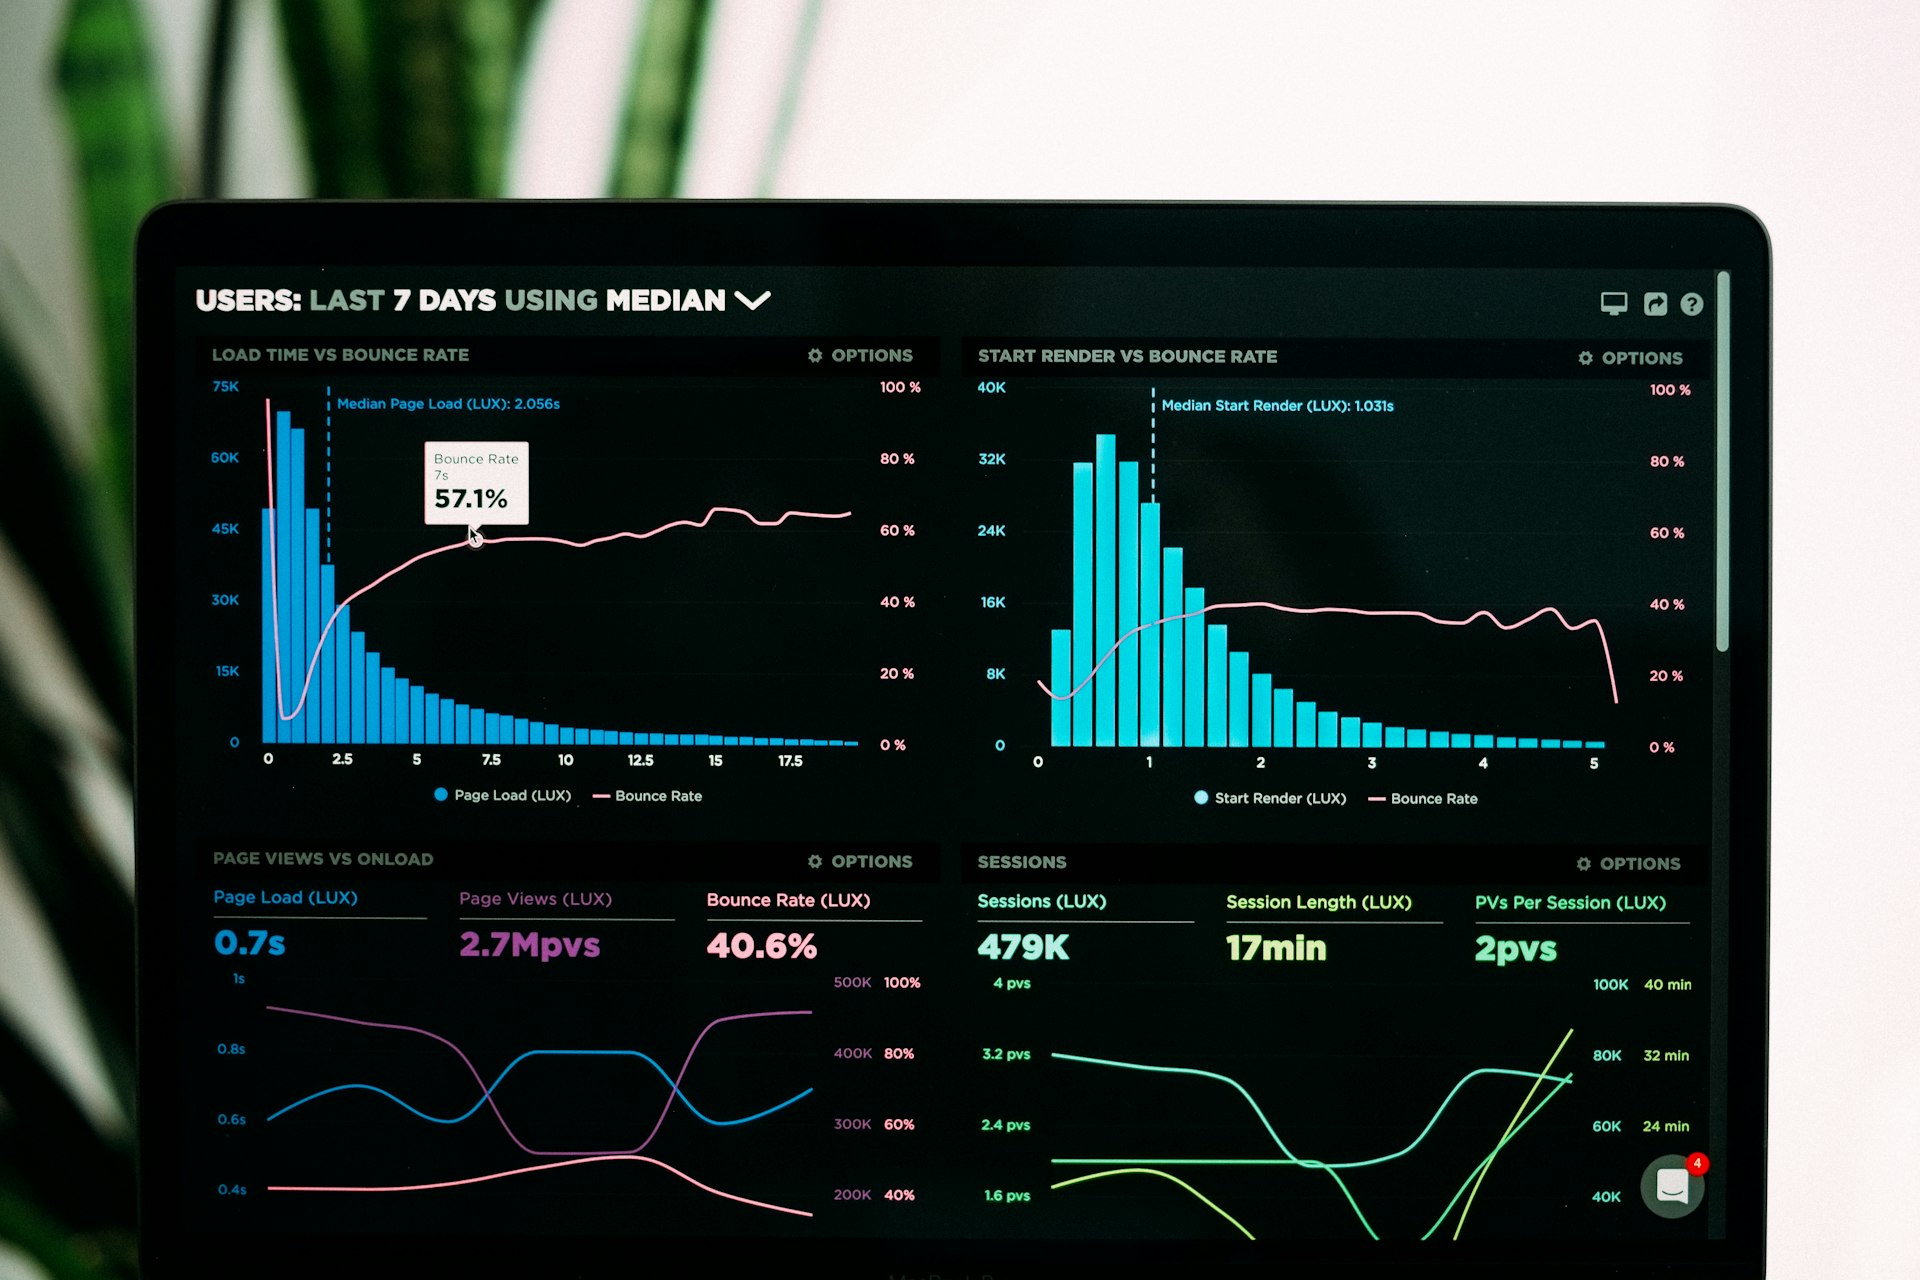
Each check has a period (how often you expect a ping) and a grace time (how late is still OK). You can also describe the schedule with a cron expression via their cronsim library. Jobs can ping on start, success, and failure so you see hung runs, not only missing ones. The dashboard live-updates; check pages keep a ping log. Public badges with hard-to-guess URLs drop onto a README or an internal status page.
Alerts go out through 25+ integrations (email, Slack, Telegram, Discord, ntfy, PagerDuty, and more). Teams get projects, members, and read-only access. WebAuthn 2FA is optional. There is an HTTP API if you want to create checks from Terraform or a bootstrap script.
Why self-host?
Ping URLs are a map of every job you care about. Hosting Healthchecks on your own box keeps that map, plus the last 100 pings per check (configurable), off a third-party SaaS. Useful when backup scripts include hostnames, or when you would rather not have a US-hosted monitor as the only thing that knows your Canadian batch jobs exist.
The hosted healthchecks.io service is fine for personal use. Self-host when you want unlimited checks without a plan, SMTP that already lives on your Mail-in-a-Box, or a monitor that still works if an external SaaS has a bad day. BSD-3-Clause is easy for internal ops; you are not fighting AGPL if you wrap this for a client VPS.
Tradeoff: this is a real Django app. SQLite works for a homelab. Production wants PostgreSQL or MySQL/MariaDB, plus a process that runs sendalerts continuously. If that worker is down, the UI still shows state, but nobody gets paged. SMTP must work or login links and email alerts never leave the box. Optional S3-compatible storage can hold large ping bodies; remember to run their prune commands if you use it.
Quick start
Official image: healthchecks/healthchecks on Docker Hub. Point SITE_ROOT at your public HTTPS URL, set a SECRET_KEY, and give it a database. Bare metal is Python 3.12+, pip install -r requirements.txt, ./manage.py migrate, then runserver (or gunicorn) plus:
./manage.py sendalerts
./manage.py sendreports --loop
A one-line ping from crontab looks like this (UUID comes from the check you create in the UI):
0 3 * * * /usr/local/bin/backup.sh && curl -fsS -m 10 --retry 5 https://hc.example.ca/ping/YOUR-UUIDPut TLS and auth in front. Enable WebAuthn by setting RP_ID to the hostname without scheme. If you terminate login at Authelia or similar, upstream supports a trusted REMOTE_USER_HEADER; strip that header at the proxy so clients cannot spoof it.
Who it is for
Good fit: anyone with crontab they actually rely on; homelabs pairing Healthchecks with GoCron or systemd timers; shops that already run Django and Postgres; teams who want job history without standing up a full observability stack.
Skip it: if you only need "is the homepage returning 200" (use Kuma or Gatus); if you cannot keep SMTP and sendalerts running; if a handful of jobs on healthchecks.io already covers you and you do not want another container.
Hosting in Canada
Healthchecks is light compared with the jobs it watches. A small CloudBox VPS with Postgres, daily DB dumps, and HTTPS is enough for personal and small-team use. Keep ping endpoints on a hostname you control so backup boxes inside Canada talk to a monitor in the same region. Back up the database; the ping log is how you prove a job ran last Tuesday.
Bottom line
Healthchecks is the missing page for silent cron. Uptime tools watch the front door. This one notices when the night shift never clocked in. Run it next to your schedulers, ping from the last line of every script that matters, and treat sendalerts like production.
Talk with Swift Host if you want a Canadian VPS for Healthchecks plus the jobs it monitors: TLS, Postgres backups, and SMTP that actually delivers. We are in St. Albert and actually answer the phone.